Mochi 1: what the repository publishes
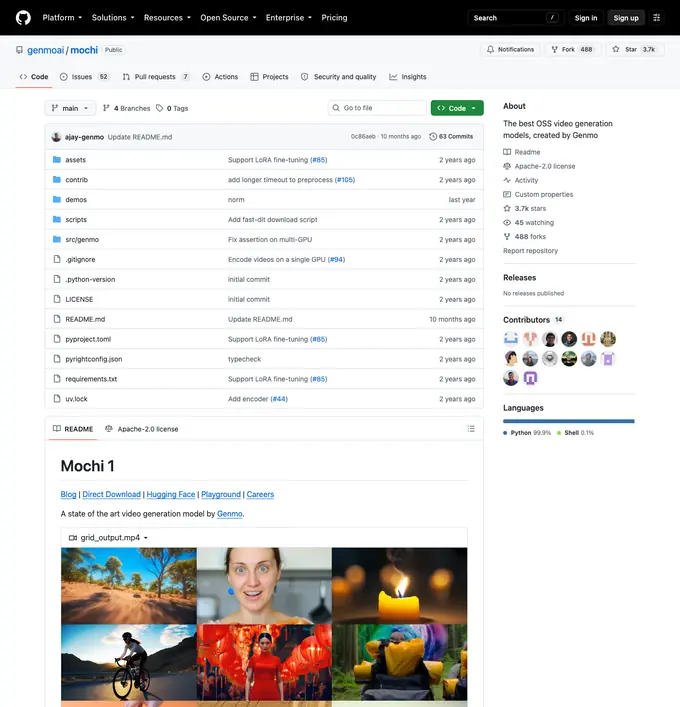
Mochi 1 publishes a 10 billion parameter model under Apache 2.0, with a separately stated 362M autoencoder. The repository asks for about 60GB of VRAM on a single GPU and recommends at least one H100, at 480p. As of 2026-09-12.
| Field | What is stated | Detail |
|---|---|---|
| Licence | Apache 2.0 | Stated in the repository |
| Size | 10 billion parameters | Plus a 362M video autoencoder |
| Hardware | About 60GB VRAM on a single GPU | At least one H100 recommended |
| Resolution | 480p | Described as the current capability |
| Length | No length recorded | The repository states a present resolution instead |
Inclusion rule. The same five fields for every family here. A field the repository does not state is recorded as not stated rather than estimated from the parameter count. Order. Fixed field order, identical on every family page.
1Permissive licence, demanding hardware, modest resolution
These three facts together describe a research release rather than a production drop-in. The licence imposes nothing, the hardware asks for a data-centre card, and the output resolution is the lowest stated in this register.
That combination is worth naming because the word open covers it and covers a 4GB model equally, and those two are not alternatives for the same team.
2Naming the recommended card is more useful than a bare figure
Sixty gigabytes narrows the field; recommending at least one H100 names it. A reader can price an H100 hour in a minute, and cannot price sixty gigabytes without first deciding which card supplies it.
Eight of the 15 families in this register name a card or a card generation. Those are the entries whose hardware cost can be estimated from published material alone.
3A stated present limit is not a permanent one
The repository describes 480p as the current capability, which is a form of words that says more is intended. This register records it as stated, with the date, and will change the row when the repository does.
Recording the qualifier matters here: a flat 480p row would read as a property of the model rather than as a snapshot of a release.
4The same field, across every family
| Family | Licence |
|---|---|
| Allegro | apache-2.0 |
| CogVideoX | Split by model size |
| Cosmos Predict 2.5 | NVIDIA Open Model License |
| FramePack | Apache 2.0 |
| HunyuanVideo | tencent-hunyuan-community |
| LongCat-Video | MIT License |
| LTX-Video | Apache 2.0 |
| MAGI-1 | Apache License 2.0 |
| Mochi 1 | Apache 2.0 |
| Open-Sora | Apache 2.0 |
| Pyramid Flow | stabilityai-ai-community |
| SkyReels-V2 | skywork-license |
| Stable Video Diffusion | stable-video-diffusion-community |
| Step-Video-T2V | MIT |
| Wan | Apache 2.0 |
Inclusion rule. Families whose vendor has published weights openly. A family whose repository does not state this particular field keeps its row, marked hollow. Order. Alphabetical by family name.
| Family | Size |
|---|---|
| Allegro | VAE 175M and DiT 2.8B |
| CogVideoX | 2B and 5B, carried in the model names |
| Cosmos Predict 2.5 | 2,059,174,912 parameters |
| FramePack | 13B models |
| HunyuanVideo | Over 13 billion parameters |
| LongCat-Video | 13.6B parameters |
| LTX-Video | A 13B model |
| MAGI-1 | 24B and 4.5B models |
| Mochi 1 | 10 billion parameters |
| Open-Sora | An 11B model |
| Pyramid Flow | No parameter count recorded |
| SkyReels-V2 | 1.3B, 5B and 14B variants |
| Stable Video Diffusion | 2B params |
| Step-Video-T2V | 30 billion parameters |
| Wan | A 5B text-to-video and image-to-video model |
Inclusion rule. Families whose vendor has published weights openly. A family whose repository does not state this particular field keeps its row, marked hollow. Order. Alphabetical by family name.
| Family | Hardware |
|---|---|
| Allegro | 9.3G BF16 with cpu_offload |
| CogVideoX | From 4GB in FP16 on the 2B |
| Cosmos Predict 2.5 | 32.54 GB of GPU VRAM |
| FramePack | 6GB minimum for 1800 frames at 30fps |
| HunyuanVideo | 60GB peak at 720px1280px, 129 frames |
| LongCat-Video | No memory figure recorded |
| LTX-Video | No minimum stated |
| MAGI-1 | H100 or H800 x 8 for the 24B |
| Mochi 1 | About 60GB VRAM on a single GPU |
| Open-Sora | 60.3GB peak at 768px on one GPU |
| Pyramid Flow | No memory figure recorded |
| SkyReels-V2 | About 14.7GB peak on the 1.3B at 540P |
| Stable Video Diffusion | About 180s on an A100 80GB card |
| Step-Video-T2V | 78.55 GB peak at 768px768px204f |
| Wan | A consumer 4090 on the 5B release |
Inclusion rule. Families whose vendor has published weights openly. A family whose repository does not state this particular field keeps its row, marked hollow. Order. Alphabetical by family name.
- LicenceApache 2.0stated in the repository
- Model sizeA 10 billion parameter diffusion model, with a 362M parameter video autoencoderstated in the repository
- HardwareApproximately 60GB VRAM on a single GPU, with at least one H100 recommendedthe vendor's own figure
- Resolution480p, described as the current capabilitystated as a present limit
5Running the model without the hardware
Instead of local hardware for “Mochi 1”, SceneMixer runs hosted models; its guides describe the result:
Seedance 2.0 (ByteDance's video model family) is one of the strongest engines for vertical short drama in 2026.
SceneMixer, Seedance 2.0 in a Real Short-Drama Pipeline (read 2026-10-13)
SceneMixer writes dialogue into the script analysis, assigns each line to a shot with a speaker and a short delivery note, and the video model performs it — picture and audio generated together, so the mouth forms that sentence in the language you chose.
SceneMixer, AI Dialogue Generator (read 2026-10-13)
6Sources
Read from github.com/genmoai on 2026-09-12. Hardware figures across every family are collected on requirements; the licence column is set out on licence and what counts as a published weight is on the method page. Previous family: CogVideoX. Next family: Allegro.